Nginx was never built for Kubernetes — it was retrofitted. Traefik was built from scratch for dynamic, container-first environments. In this post we cover what Traefik actually is, how its routing pipeline works internally, break down its architecture component by component, and close with a production-grade migration from Nginx Ingress Controller to Traefik — real configs, real YAML, no hand-waving.
What Is Traefik?
Traefik (pronounced traffic) is a cloud-native reverse proxy and load balancer written in Go, purpose-built for container orchestration environments. Unlike Nginx — a high-performance web server originally designed for static content that was later wrapped into a Kubernetes Ingress Controller — Traefik was designed from day one around the idea that infrastructure is dynamic and that routing config should never require a process restart.
The core proposition is simple: Traefik watches your infrastructure and auto-configures itself. No manual config reloads. No annotation soup. When a new Kubernetes Service appears or an IngressRoute is updated, Traefik detects it, builds the routing rule, and starts forwarding traffic — without a restart, without regenerating a config file, without dropping active connections.
The Provider Model — The Key Concept
Traefik uses a provider model: it subscribes to infrastructure sources — Kubernetes, Docker, Consul, Nomad, or even plain files — called "providers." The Kubernetes provider watches the cluster API server continuously using informers. When any resource changes, Traefik rebuilds its internal routing table on the fly. No static configs. No nginx.conf. No process restarts.
Originally released in 2015 by Containous (now Traefik Labs), Traefik ships as a single Go binary with no external dependencies, is deployed as a Kubernetes Deployment or DaemonSet, and as of v3 (current stable) natively supports HTTP, HTTPS, TCP, UDP, gRPC, and WebSockets routing — all declaratively configured via Kubernetes CRDs.
How Traefik Works — The Request Pipeline
Understanding Traefik's internal pipeline is what separates operators who "just apply the Helm chart" from those who can actually debug it when something breaks. Every request Traefik handles passes through a fixed, ordered pipeline. Click each stage below to understand exactly what happens at that layer:
Traefik Request Pipeline — Interactive
1. Entrypoints
Entrypoints are static listeners defined at startup — a port and protocol Traefik binds to. Common examples: :80 (web), :443 (websecure), :8080 (dashboard). These are the only things in Traefik that require a restart to change. Everything downstream is fully dynamic and hot-reloaded.
2. Routers
Routers are the decision layer. They match incoming requests against rules using Traefik's rule syntax: Host(`api.example.com`), PathPrefix(`/api`), Headers(`X-Custom`, `value`), or any combination using && and ||. Each Router is bound to one or more Entrypoints and connects to a Service — optionally through a named Middleware chain. Routers are defined in IngressRoute CRDs or standard Ingress annotations.
3. Middlewares
Middlewares transform requests or responses before they reach the backend. They are first-class Kubernetes objects (Middleware CRD), composable, and reusable across any number of Routers. Built-in middlewares cover: rate limiting, authentication (BasicAuth, ForwardAuth), CORS, circuit breakers, retry logic, redirect schemes, request body size limits, strip prefix, and header manipulation. Define them once, reference them by name everywhere — this is what kills the annotation sprawl.
4. Services
Services define where traffic lands after routing. A Traefik Service maps to a Kubernetes Service (via ClusterIP) and supports load balancing strategies — round-robin by default, or weighted backends for canary and blue/green deployments. You shift traffic between versions by changing a weight in Git. No kubectl patch, no imperative commands.
5. Providers
The Kubernetes provider bridges Traefik and your cluster. It continuously watches the Kubernetes API server — Ingress objects, IngressRoute CRDs, Services, and Endpoints — using informers, and reflects changes into Traefik's routing table instantly. This is what makes Traefik fundamentally different from Nginx: the routing config is not a file that gets rewritten and reloaded — it is a live in-memory data structure that updates without touching active connections.
Why Zero-Reload Matters at Scale
In Nginx Ingress, every config change — new Ingress, annotation update, new backend service — triggers a full nginx.conf regeneration and a graceful reload. At scale with hundreds of services and frequent deployments, those reloads happen constantly and cause latency spikes as Nginx drains and reestablishes connections. Traefik's dynamic routing eliminates this entirely. Config changes propagate without touching a single active connection.
Traefik Architecture in Kubernetes
In a Kubernetes cluster, Traefik runs as a Deployment (or DaemonSet on edge nodes), sits at the data plane edge, and bridges external traffic to internal Services. It registers either as a standard Kubernetes Ingress Controller for compatibility, or via its own IngressRoute CRDs for full capability.
Traefik Ingress Architecture — Full Stack
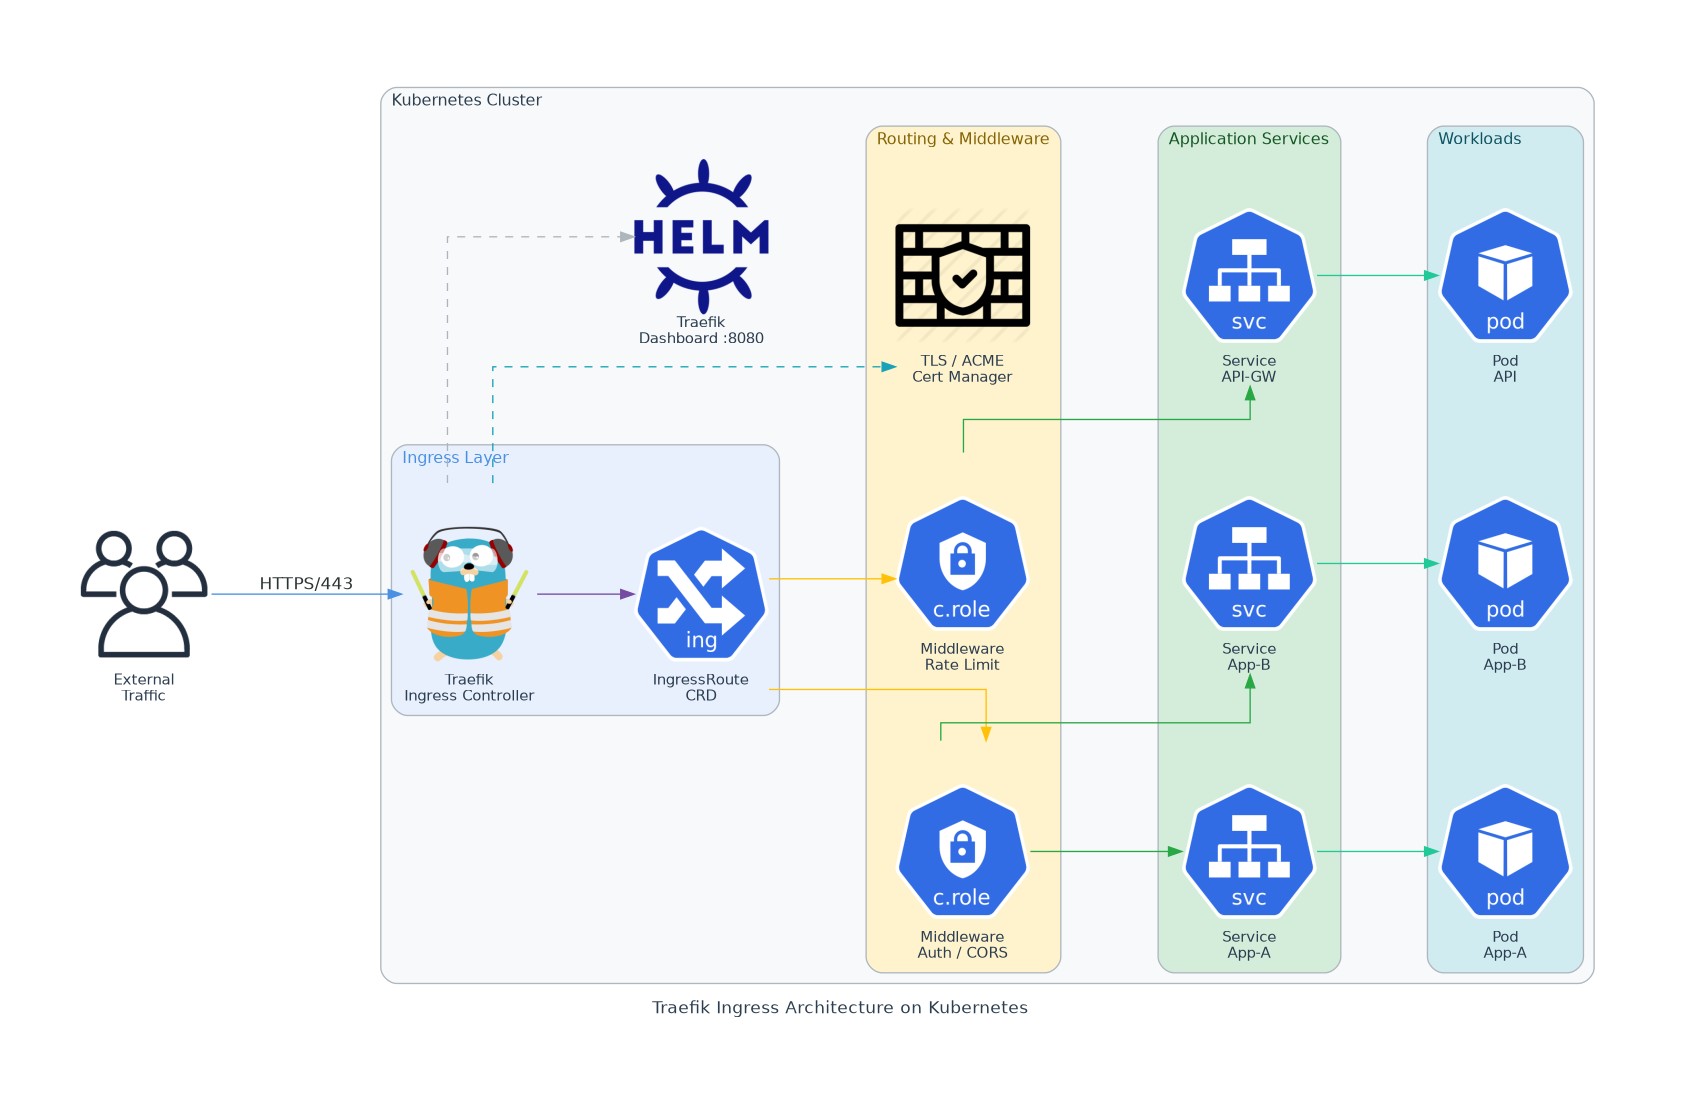
Figure 1 — External traffic arrives at Traefik's Entrypoints. IngressRoute CRDs define which Routers handle which hostnames and paths. Middleware chains apply rate limiting, auth, and headers before traffic reaches Kubernetes Services. TLS is terminated natively via built-in ACME. The Traefik Dashboard provides real-time observability of the full routing table.
Core Architecture Components
| Component | Role | Kubernetes Equivalent |
|---|---|---|
| Entrypoints | Static port listeners (80, 443, 8080). Defined at startup. Protocol-aware — TCP, UDP, or HTTP. | NodePort / LoadBalancer ports |
| Routers | Match requests via composable rule expressions. Attach to Entrypoints, apply Middlewares, forward to Services. Defined in IngressRoute CRDs. | Replaces Ingress rules and annotations |
| Middlewares | Request/response transformers — rate limiting, auth, CORS, circuit breakers, retries, headers. Defined as standalone CRDs, reusable by name across any Router. | Replaces nginx.ingress.kubernetes.io/* annotations |
| Services | Backend definitions with load balancing strategy. Maps to Kubernetes Services. Supports weighted routing for canary deployments natively. | Kubernetes Service + LB config |
| Providers | Infrastructure watchers. The Kubernetes provider reads IngressRoute, Ingress, Services, Endpoints from the API server and drives Traefik's live routing table via informers. | Watches Kubernetes API (informers) |
| TLS / ACME | Built-in Let's Encrypt integration. Issues and auto-renews certificates using HTTP-01 or TLS-ALPN-01 challenges. Stores certs in a local JSON file (PVC-backed in production). | Replaces cert-manager + ClusterIssuer |
| Dashboard | Built-in real-time web UI showing all Entrypoints, Routers, Middlewares, and Services with health status. Exposes Prometheus metrics on :8080/metrics and OpenTelemetry tracing. |
No equivalent in Nginx — requires external tooling |
IngressRoute CRDs vs Standard Kubernetes Ingress
Traefik supports two configuration modes. Standard Ingress objects work for drop-in compatibility — useful if you have Helm charts that generate Ingress manifests you don't control. Traefik's native IngressRoute CRDs unlock the full feature set: explicit Middleware chaining, TCP and UDP routing, advanced load balancing, and priority-based routing. For any service you control, always use IngressRoute.
💡 IngressRoute vs Ingress — Rule of Thumb
Use standard Ingress only when a third-party Helm chart generates Ingress objects automatically and you can't modify them. For any workload you own and manage, use IngressRoute CRDs — they're cleaner, explicitly express your Middleware chain, and produce reviewable, meaningful diffs in pull requests. Annotations cannot do that.
Traefik vs Nginx Ingress — Honest Production Comparison
This is not "Traefik wins everything." Here's an honest breakdown of what actually matters in a production cluster:
| Dimension | Nginx Ingress | Traefik v3 |
|---|---|---|
| Config reload behavior | Full nginx.conf regeneration and reload on every Ingress or annotation change. At scale with frequent deployments: constant reloads, latency spikes, connection drains. | Zero-downtime hot routing updates. In-memory routing table updated live. No dropped connections, no reload delay. |
| TLS / certificate management | Requires cert-manager + ClusterIssuer for Let's Encrypt. Adds another operator, another CRD layer, another thing to version and upgrade. | Built-in ACME. Traefik issues and renews certificates natively. One fewer dependency to maintain. |
| Routing configuration | Annotation-driven. Complex rules become long chains of nginx.ingress.kubernetes.io/* annotations — unreadable in PRs, impossible to diff meaningfully. |
IngressRoute CRDs. Explicit, structured YAML. Readable diffs, clean Git history, proper GitOps flow. |
| Middleware / Auth | Via annotations or Lua snippets. Fragile, cluster-specific, hard to test in isolation, non-portable. | First-class Middleware CRDs. Defined once, referenced by name from any IngressRoute. Fully composable and reusable. |
| TCP / UDP routing | Minimal. Requires separate controllers or nginx config snippets with significant caveats. | Native IngressRouteTCP and IngressRouteUDP CRDs. Works out of the box. |
| Observability | Prometheus metrics via stub_status. Basic. No built-in dashboard — requires external tooling for routing visibility. | Built-in dashboard UI, rich Prometheus metrics, OpenTelemetry tracing support, per-router request duration histograms. |
| GitOps compatibility | Annotations scatter config across dozens of Ingress objects. Hard to manage declaratively or meaningfully review in ArgoCD / Flux diffs. | All routing config is Kubernetes-native CRDs. ArgoCD, Flux, any GitOps tool treats them as first-class resources with proper diff and sync. |
| Raw throughput | Extremely high. Battle-tested at massive scale for pure proxy performance benchmarks. | Slightly lower raw TPS than Nginx at extreme load. Negligible for most real-world production workloads. |
| Operational familiarity | Most ops teams have existing Nginx knowledge. Huge community, existing runbooks. | New CRD model. Roughly a day to internalize. Documentation is excellent and the model is simpler than it looks. |
⚠️ When to Stay on Nginx
Stick with Nginx Ingress if your team has deep established Nginx expertise, your annotation count is small and stable, you depend on Nginx-specific features like custom Lua scripting or OpenResty modules, or you're running at extreme TPS where raw proxy throughput is the primary constraint. There is no universal answer — but for teams running GitOps with many services, Traefik's model is objectively cleaner at every layer.
Production Example: Replacing Nginx Ingress with Traefik
The scenario: a production cluster running two services (api-service and frontend-service) with TLS, currently on Nginx Ingress Controller with cert-manager. Goal: migrate to Traefik with zero downtime by running both controllers in parallel and cutting over service by service.
Before vs After — Nginx to Traefik Migration
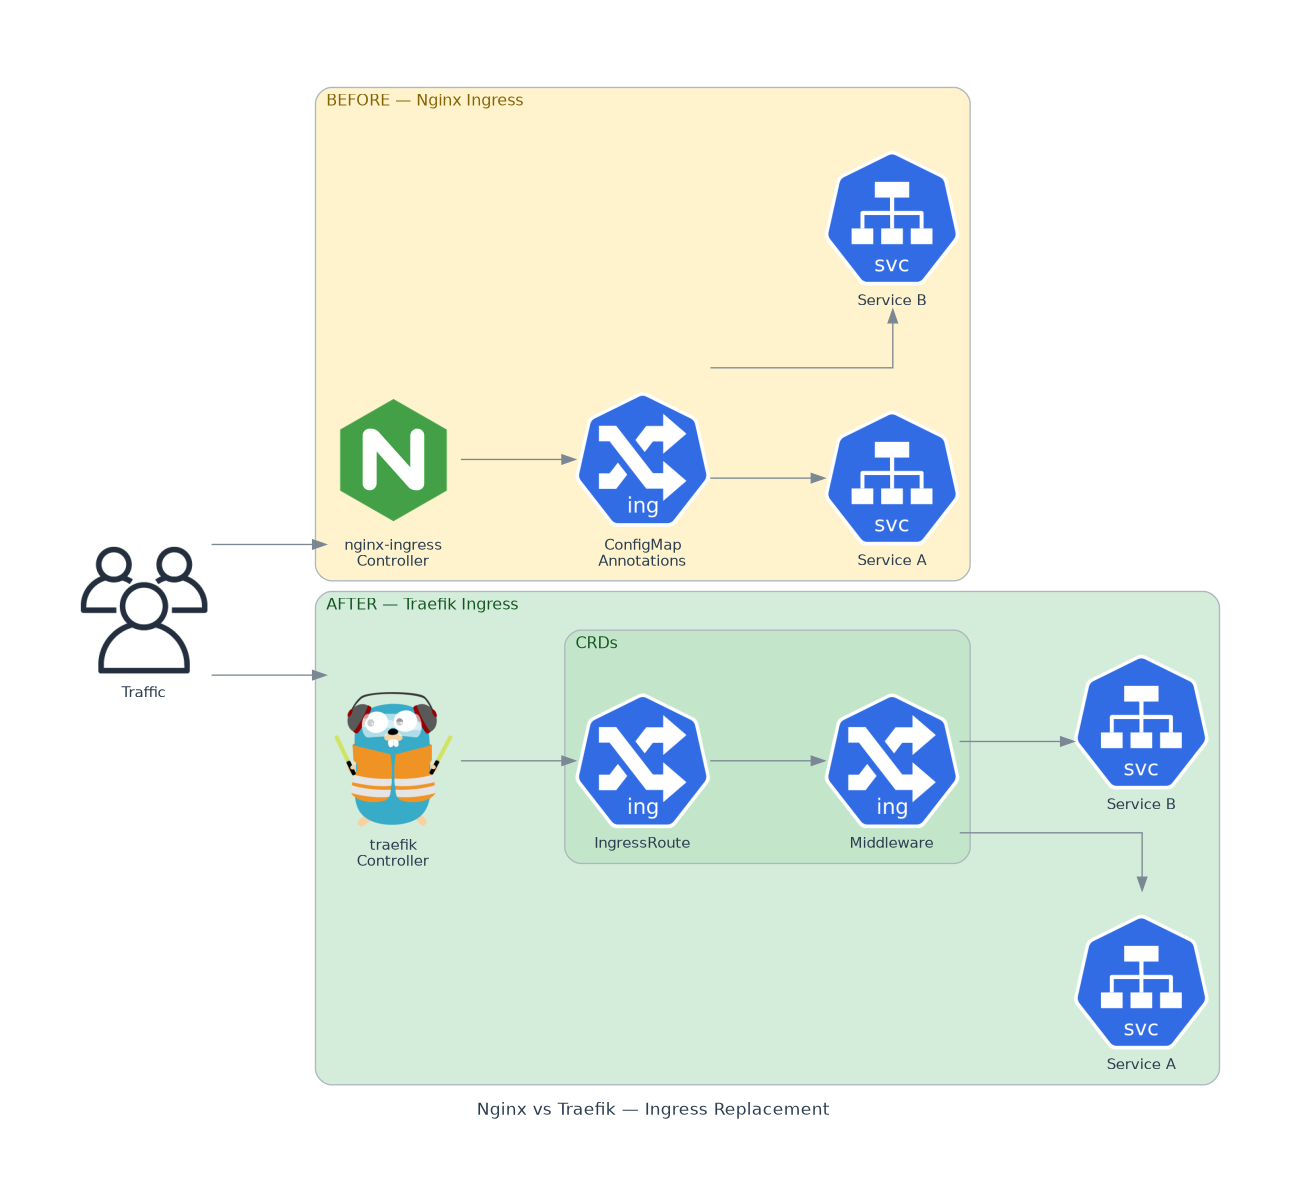
Figure 2 — Before: Nginx controller translates annotation-heavy Ingress objects into nginx.conf and reloads on every change. After: Traefik watches IngressRoute CRDs directly, updates its in-memory routing table with zero reloads, no dropped connections, and no cert-manager dependency.
1 Install Traefik via Helm — Alongside Nginx (Parallel Operation)
# Add Traefik Helm repo
helm repo add traefik https://traefik.github.io/charts
helm repo update

# Install Traefik — NOT as the default IngressClass yet
helm install traefik traefik/traefik \
  --namespace traefik \
  --create-namespace \
  --set deployment.replicas=2 \
  --set ports.websecure.tls.enabled=true \
  --set providers.kubernetesCRD.enabled=true \
  --set providers.kubernetesIngress.enabled=true \
  --set ingressClass.enabled=true \
  --set ingressClass.isDefaultClass=false \
  --set logs.access.enabled=true \
  --set metrics.prometheus.enabled=true

# Verify Traefik pods are running
kubectl get pods -n traefik
# NAME                       READY   STATUS    RESTARTS
# traefik-7d9b8f6c4d-2xkpv   1/1     Running   0
# traefik-7d9b8f6c4d-9rqnm   1/1     Running   0
ℹ️ Running Both Controllers in Parallel
Setting isDefaultClass=false keeps all existing Nginx Ingress objects fully active. Traefik will only handle resources that explicitly set ingressClassName: traefik or use IngressRoute CRDs. This lets you migrate services one at a time, validate each in production, and flip the default IngressClass only when every service has been migrated and tested.
2 The Old Nginx Ingress — What We Are Replacing
# ── BEFORE: nginx-ingress.yaml ──────────────────────────────────────────────
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: app-ingress
  namespace: production
  annotations:
    kubernetes.io/ingress.class: "nginx"
    nginx.ingress.kubernetes.io/ssl-redirect: "true"
    nginx.ingress.kubernetes.io/proxy-body-size: "50m"
    nginx.ingress.kubernetes.io/limit-rps: "100"
    nginx.ingress.kubernetes.io/limit-connections: "20"
    cert-manager.io/cluster-issuer: "letsencrypt-prod"
    # ...and 10 more annotations you've forgotten the meaning of
spec:
  tls:
    - hosts: ["api.example.com", "app.example.com"]
      secretName: app-tls-secret
  rules:
    - host: api.example.com
      http:
        paths:
          - path: /
            pathType: Prefix
            backend:
              service:
                name: api-service
                port:
                  number: 8080
    - host: app.example.com
      http:
        paths:
          - path: /
            pathType: Prefix
            backend:
              service:
                name: frontend-service
                port:
                  number: 80
3 Create Reusable Middleware Objects
This is where Traefik pays off immediately. Define rate limiting, redirects, and security headers once — reference them by name from any route forever. No more duplicating annotations across every Ingress object.
# ── traefik-middlewares.yaml ────────────────────────────────────────────────
---
# HTTPS redirect — applied to all HTTP entrypoint routes
apiVersion: traefik.io/v1alpha1
kind: Middleware
metadata:
  name: redirect-https
  namespace: production
spec:
  redirectScheme:
    scheme: https
    permanent: true
---
# Rate limiting — 100 req/min average, burst of 200
apiVersion: traefik.io/v1alpha1
kind: Middleware
metadata:
  name: rate-limit
  namespace: production
spec:
  rateLimit:
    average: 100
    burst: 200
    period: 1m
---
# Request body size limit (replaces proxy-body-size annotation)
apiVersion: traefik.io/v1alpha1
kind: Middleware
metadata:
  name: body-limit
  namespace: production
spec:
  buffering:
    maxRequestBodyBytes: 52428800   # 50MB
---
# Security headers — applied globally to all routes
apiVersion: traefik.io/v1alpha1
kind: Middleware
metadata:
  name: secure-headers
  namespace: production
spec:
  headers:
    frameDeny: true
    browserXssFilter: true
    contentTypeNosniff: true
    stsSeconds: 31536000
    stsIncludeSubdomains: true

# Apply: kubectl apply -f traefik-middlewares.yaml
4 Create IngressRoute CRDs — The Traefik Way
These replace the Nginx Ingress entirely. Clean YAML, explicit middleware references, TLS handled natively — no cert-manager.
# ── traefik-ingressroutes.yaml ──────────────────────────────────────────────
---
# API service — HTTPS with rate limiting, body limit, and security headers
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: api-route
  namespace: production
spec:
  entryPoints:
    - websecure
  routes:
    - match: Host(`api.example.com`)
      kind: Rule
      middlewares:
        - name: rate-limit
          namespace: production
        - name: body-limit
          namespace: production
        - name: secure-headers
          namespace: production
      services:
        - name: api-service
          port: 8080
  tls:
    certResolver: letsencrypt     # Traefik handles this — no cert-manager needed
---
# Frontend — HTTPS with rate limiting and security headers
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: frontend-route
  namespace: production
spec:
  entryPoints:
    - websecure
  routes:
    - match: Host(`app.example.com`)
      kind: Rule
      middlewares:
        - name: rate-limit
          namespace: production
        - name: secure-headers
          namespace: production
      services:
        - name: frontend-service
          port: 80
  tls:
    certResolver: letsencrypt
---
# HTTP catch-all redirect to HTTPS
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: redirect-http
  namespace: production
spec:
  entryPoints:
    - web
  routes:
    - match: HostRegexp(`{host:.+}`)
      kind: Rule
      priority: 1
      middlewares:
        - name: redirect-https
          namespace: production
      services:
        - name: noop@internal
          kind: TraefikService
5 Configure ACME (Let's Encrypt) in Helm Values
Add to your Helm values file and upgrade the release. This replaces cert-manager for standard Let's Encrypt use cases.
# ── traefik-values.yaml (Helm override) ─────────────────────────────────────
additionalArguments:
  - "[email protected]"
  - "--certificatesresolvers.letsencrypt.acme.storage=/data/acme.json"
  - "--certificatesresolvers.letsencrypt.acme.tlschallenge=true"
  # Test with staging first:
  # - "--certificatesresolvers.letsencrypt.acme.caserver=https://acme-staging-v02.api.letsencrypt.org/directory"

persistence:
  enabled: true          # CRITICAL — without this, acme.json is lost on pod restart
  size: 128Mi
  storageClass: "local-path"

deployment:
  replicas: 2

resources:
  requests:
    cpu: 200m
    memory: 256Mi
  limits:
    cpu: 500m
    memory: 512Mi

# Apply the updated release:
# helm upgrade traefik traefik/traefik -n traefik -f traefik-values.yaml
⚠️ ACME Rate Limits Will Ruin Your Day
If Traefik restarts without persistent storage configured for /data/acme.json, it loses all issued certificates and re-requests them from Let's Encrypt. Hit the rate limit — 5 duplicate certificates per domain per week — and you are locked out for 7 days. Always configure PVC persistence before enabling ACME in production. Always test with the Let's Encrypt staging endpoint first. The staging server has no rate limits and issues untrusted certs — perfect for verifying the ACME flow before going live.
6 Validate and Cut Over
# ── Validate before touching DNS ────────────────────────────────────────────

# Check Traefik pods are healthy with 0 restarts
kubectl get pods -n traefik

# Verify IngressRoutes are registered
kubectl get ingressroute -n production
# NAME              AGE
# api-route         2m
# frontend-route    2m
# redirect-http     2m

# Access Traefik dashboard — verify all routers show as green
kubectl port-forward -n traefik \
  $(kubectl get pod -n traefik -l app.kubernetes.io/name=traefik -o name | head -1) \
  9000:9000
# Open: http://localhost:9000/dashboard

# Test routing BEFORE DNS cutover — curl against Traefik's external IP directly
TRAEFIK_IP=$(kubectl get svc -n traefik traefik -o jsonpath='{.status.loadBalancer.ingress[0].ip}')

curl --resolve "api.example.com:443:${TRAEFIK_IP}" \
     https://api.example.com/healthz -k -w "%{http_code}\n"
# Expected: 200

curl --resolve "app.example.com:443:${TRAEFIK_IP}" \
     https://app.example.com/ -k -w "%{http_code}\n"
# Expected: 200

# ── All good? Do the cutover ─────────────────────────────────────────────────

# Scale down Nginx Ingress Controller
kubectl scale deployment ingress-nginx-controller \
  -n ingress-nginx --replicas=0

# Get Traefik external IP and update your DNS A records / LoadBalancer selector
echo "Point DNS to: ${TRAEFIK_IP}"

# Set Traefik as the new default IngressClass
kubectl patch ingressclass traefik \
  -p '{"metadata":{"annotations":{"ingressclass.kubernetes.io/is-default-class":"true"}}}'
✓ Migration Cutover Checklist
- Traefik pods: Running, 0 restarts, both replicas up
- All IngressRoutes visible in
kubectl get ingressroute -A - Traefik Dashboard: all routers show as green / active
- ACME certs issued: check dashboard TLS section and Traefik pod logs
- curl test against Traefik IP returns HTTP 200 for all hostnames before DNS change
- Nginx scaled to 0 with no active connections in flight
- DNS records updated or LoadBalancer selector pointing to Traefik pods
- Monitor for 10 minutes post-cutover: latency, error rate, cert expiry metric
Observability — Dashboard and Prometheus Metrics
Traefik ships with a built-in dashboard on :8080/dashboard and exposes Prometheus metrics on :8080/metrics by default. If you're running kube-prometheus-stack, add a ServiceMonitor to scrape Traefik automatically:
# manifests/monitoring/traefik-servicemonitor.yaml
apiVersion: monitoring.coreos.com/v1
kind: ServiceMonitor
metadata:
  name: traefik-metrics
  namespace: monitoring
spec:
  selector:
    matchLabels:
      app.kubernetes.io/name: traefik
  namespaceSelector:
    matchNames: [traefik]
  endpoints:
    - port: metrics
      path: /metrics
      interval: 30s

# ── Key metrics to monitor and alert on ─────────────────────────
#
# traefik_router_requests_total              — RPS per router (rate)
# traefik_router_request_duration_seconds    — P50/P95/P99 latency per router
# traefik_service_requests_total             — Requests reaching backends
# traefik_service_server_up                 — Backend health (0=down, 1=up)
# traefik_tls_certs_not_after               — Certificate expiry (Unix timestamp)
#
# Alert rule example — cert expiry under 7 days:
# alert: TraefikCertExpiringSoon
#   expr: (traefik_tls_certs_not_after - time()) / 86400 < 7
#   labels:
#     severity: warning
💡 The Certificate Expiry Metric
traefik_tls_certs_not_after gives you the Unix timestamp of when each cert expires. Create an alert that fires when that value is less than 7 days from now. Since Traefik automatically renews at 30 days before expiry, a firing alert means ACME renewal silently failed — almost always because PVC persistence is misconfigured or a Let's Encrypt rate limit was hit.
This Isn't Optional Anymore — Ingress NGINX Is End-of-Life in March 2026
Important: Two Different "NGINX" Controllers
There is a critical naming confusion you need to understand before migrating. Ingress NGINX (kubernetes/ingress-nginx) — the Kubernetes community project — is what is retiring in March 2026. NGINX Ingress Controller (nginxinc/kubernetes-ingress), maintained by F5/NGINX Inc., is a separate product and remains fully supported with an active team. If you are using the F5-maintained controller, you are not affected by this EOL. Check with: kubectl get pods --all-namespaces --selector app.kubernetes.io/name=ingress-nginx
The retirement wasn't a surprise — it was years in the making. The project was maintained by one or two volunteers working evenings and weekends against an "endless flood of bugs and feature requests." The flexibility that made Ingress NGINX popular — arbitrary NGINX config directives via snippet annotations — became its biggest security liability. CVE-2025-1974 in 2025 underscored exactly how dangerous an under-resourced edge controller is. The responsible decision was to set a hard EOL date rather than pretend the project was sustainable.
The official recommendation from Kubernetes SIG Network is to migrate to either the Gateway API (the modern, long-term replacement) or a maintained alternative Ingress controller. Traefik is explicitly listed as a recommended migration target — with native Gateway API support already built into v3, meaning you can migrate to Traefik now and adopt Gateway API resources at your own pace without a second migration.
Run This Now — Audit Your Clusters
Before planning your migration, confirm exactly where you're exposed:
kubectl get pods --all-namespaces --selector app.kubernetes.io/name=ingress-nginx
Any result here is a cluster that needs to migrate. If it's empty, you're either already on an alternative controller or on the F5 NGINX controller (check with --selector app=nginx-ingress).
When Should You Switch to Traefik? (Hint: Now)
The question used to be "should we switch?" The EOL announcement changes that entirely. The question is now "which controller do we switch to, and what is our timeline?" Here is how to frame that decision:
Migrate to Traefik If...
- You want a maintained, production-ready Ingress controller with immediate parity to what Ingress NGINX provided — without a full Gateway API rewrite
- You're running GitOps (ArgoCD, Flux) and want CRD-native routing that actually produces meaningful Git diffs
- You want built-in TLS via ACME and to remove cert-manager from your dependency chain
- You need native TCP or UDP routing beyond HTTP/HTTPS without bolting on extra controllers
- You're migrating to on-prem or RKE2 and want a self-contained, cloud-agnostic ingress layer
- You want a clear future path — Traefik v3 already supports Gateway API, meaning one migration covers both the immediate EOL problem and the long-term direction
Consider Alternatives If...
- F5 NGINX Ingress Controller: Lowest friction if your team knows NGINX deeply — annotation mapping is nearly 1:1 and it's Apache 2.0 open source with a dedicated team
- Gateway API (Envoy Gateway, Cilium, GKE Gateway): Best long-term choice if you have time for a full migration — this is where the Kubernetes community is going
- HAProxy Kubernetes Ingress: Strong option for teams with HAProxy expertise or needing advanced session persistence features
- You're on a managed cloud service (EKS, GKE, AKS) — check your cloud provider's native Gateway offering first before installing a controller
Traefik's Migration Tool
Traefik Labs has open-sourced a migration tool specifically to help teams move from Ingress NGINX to Traefik IngressRoute CRDs. It converts your existing Ingress objects and annotations automatically. Combined with the parallel-controller migration approach covered in this post, this makes Traefik one of the lowest-friction migration paths available today.
Conclusion: Routing Config That Actually Belongs in Git
The fundamental difference between Nginx Ingress and Traefik is not performance — it is model. Nginx Ingress is a static config system bolted onto Kubernetes via annotation accumulation. Traefik is a dynamic routing system that treats Kubernetes CRDs as its native language, built for environments where services appear, disappear, and change constantly.
For teams running GitOps workflows, the operational gap is real. IngressRoute CRDs produce meaningful diffs in pull requests. Middlewares are explicit, named, and reusable without duplication. TLS is handled without a separate operator. And routing updates propagate without a single dropped connection.
The migration itself is low-risk when done in parallel: run both controllers simultaneously using separate IngressClasses, migrate service by service, validate with curl before touching DNS, then cut over. For a cluster with a dozen services, the migration is typically an afternoon — most of that time is reading Traefik's documentation for the first time. The CRD model is simpler than it looks.
Key Takeaways
- Traefik is dynamic by design — routing rules update live via the provider model, zero config reloads, zero dropped connections
- The pipeline: Entrypoints → Routers → Middlewares → Services — all composable, all declarative, all CRD-native
- IngressRoute CRDs replace annotation-driven Ingress objects with clean, auditable, reviewable YAML
- Middlewares are first-class citizens — define once, reference by name from any route, no duplication
- Built-in ACME handles Let's Encrypt natively — removes cert-manager from your dependency graph
- Migration is parallel and safe — run Traefik alongside Nginx using IngressClass separation, migrate service by service, cut DNS only after validation
- Always configure PVC persistence before enabling ACME — pod restart without it means re-requesting certs and hitting rate limits
"Nginx was built to serve files. Traefik was built to route services. At scale in Kubernetes, that design difference shows up in every config change, every deployment, and every incident at 2 AM."
Running Traefik on your RKE2 or on-prem clusters? Migrating from Nginx Ingress? Share your experience in the comments below, or reach out to the ClusterCraftOPS team.