Most teams meet Open Policy Agent through Gatekeeper, deciding which objects may enter the cluster. That's the famous use. The more valuable one is quieter: putting OPA behind the gateway so that every API request is authorized by one policy engine, written once, tested like code, and logged with a reason. This post is about that pattern and about what it costs you.
The problem: authorization as copy-paste
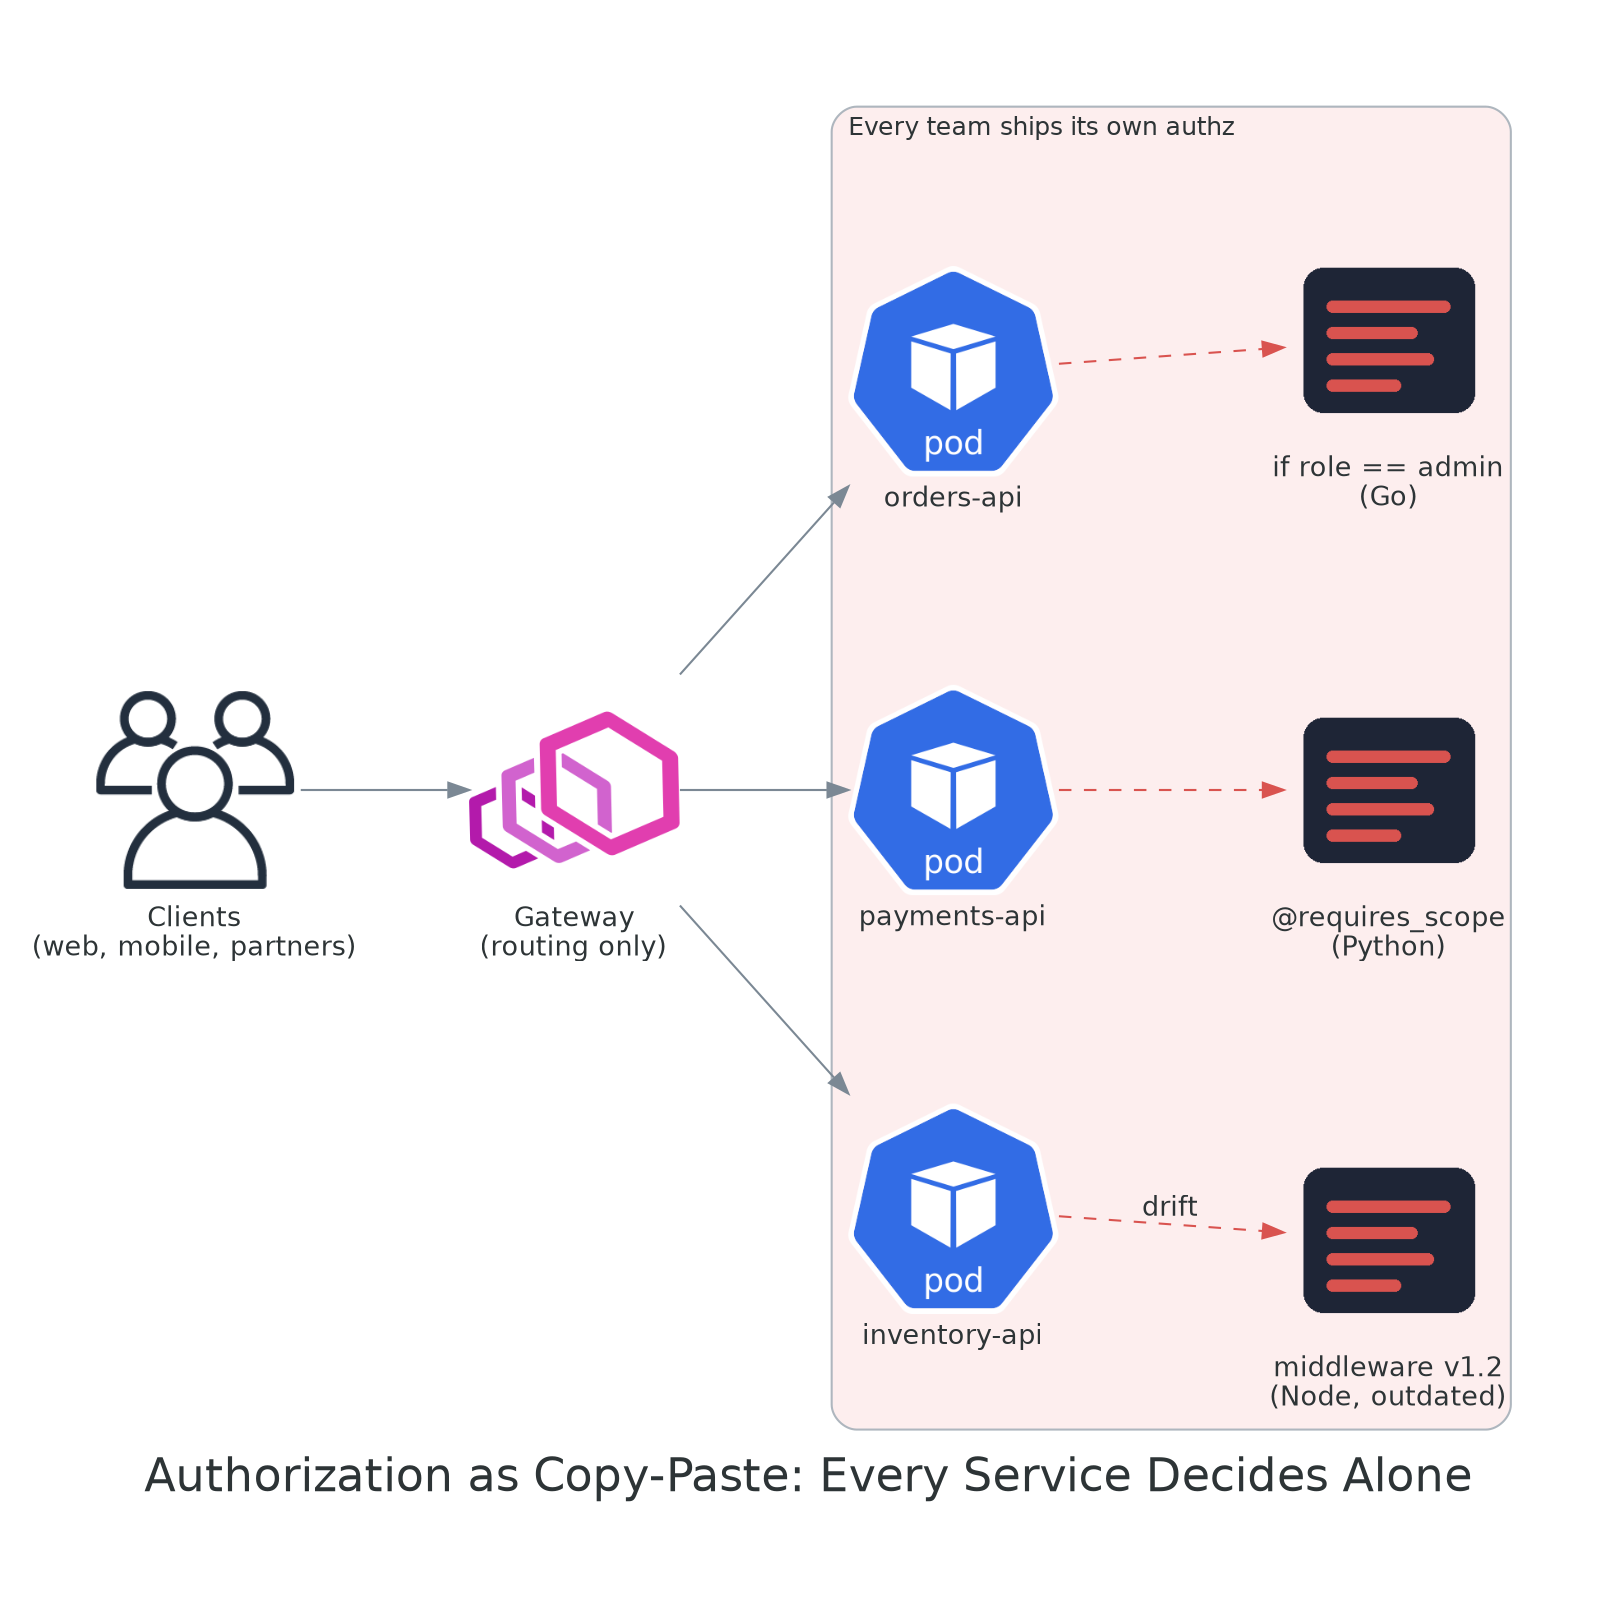
Authentication gets centralized early. Somebody wires up an identity provider, every client carries a JWT, and the gateway rejects anything unsigned. Authorization almost never gets the same treatment. The token proves who is calling; deciding what they may do is left to each service, so each team writes its own.
The orders service checks role == "admin" in Go. Payments uses a Python decorator reading scopes. Inventory imports a shared Node middleware, two major versions behind. Three services, three interpretations of the same business rule, and none of them agree on what a "tenant admin" is allowed to touch. When security asks "can a support user read another tenant's invoices?", the honest answer is "let me read three codebases and get back to you."
It's a cross-cutting concern re-implemented per workload, held together by the people who remember how it fits and every release widens the gap between what the policy document says and what the code actually enforces.
The pattern: one decision point at the edge
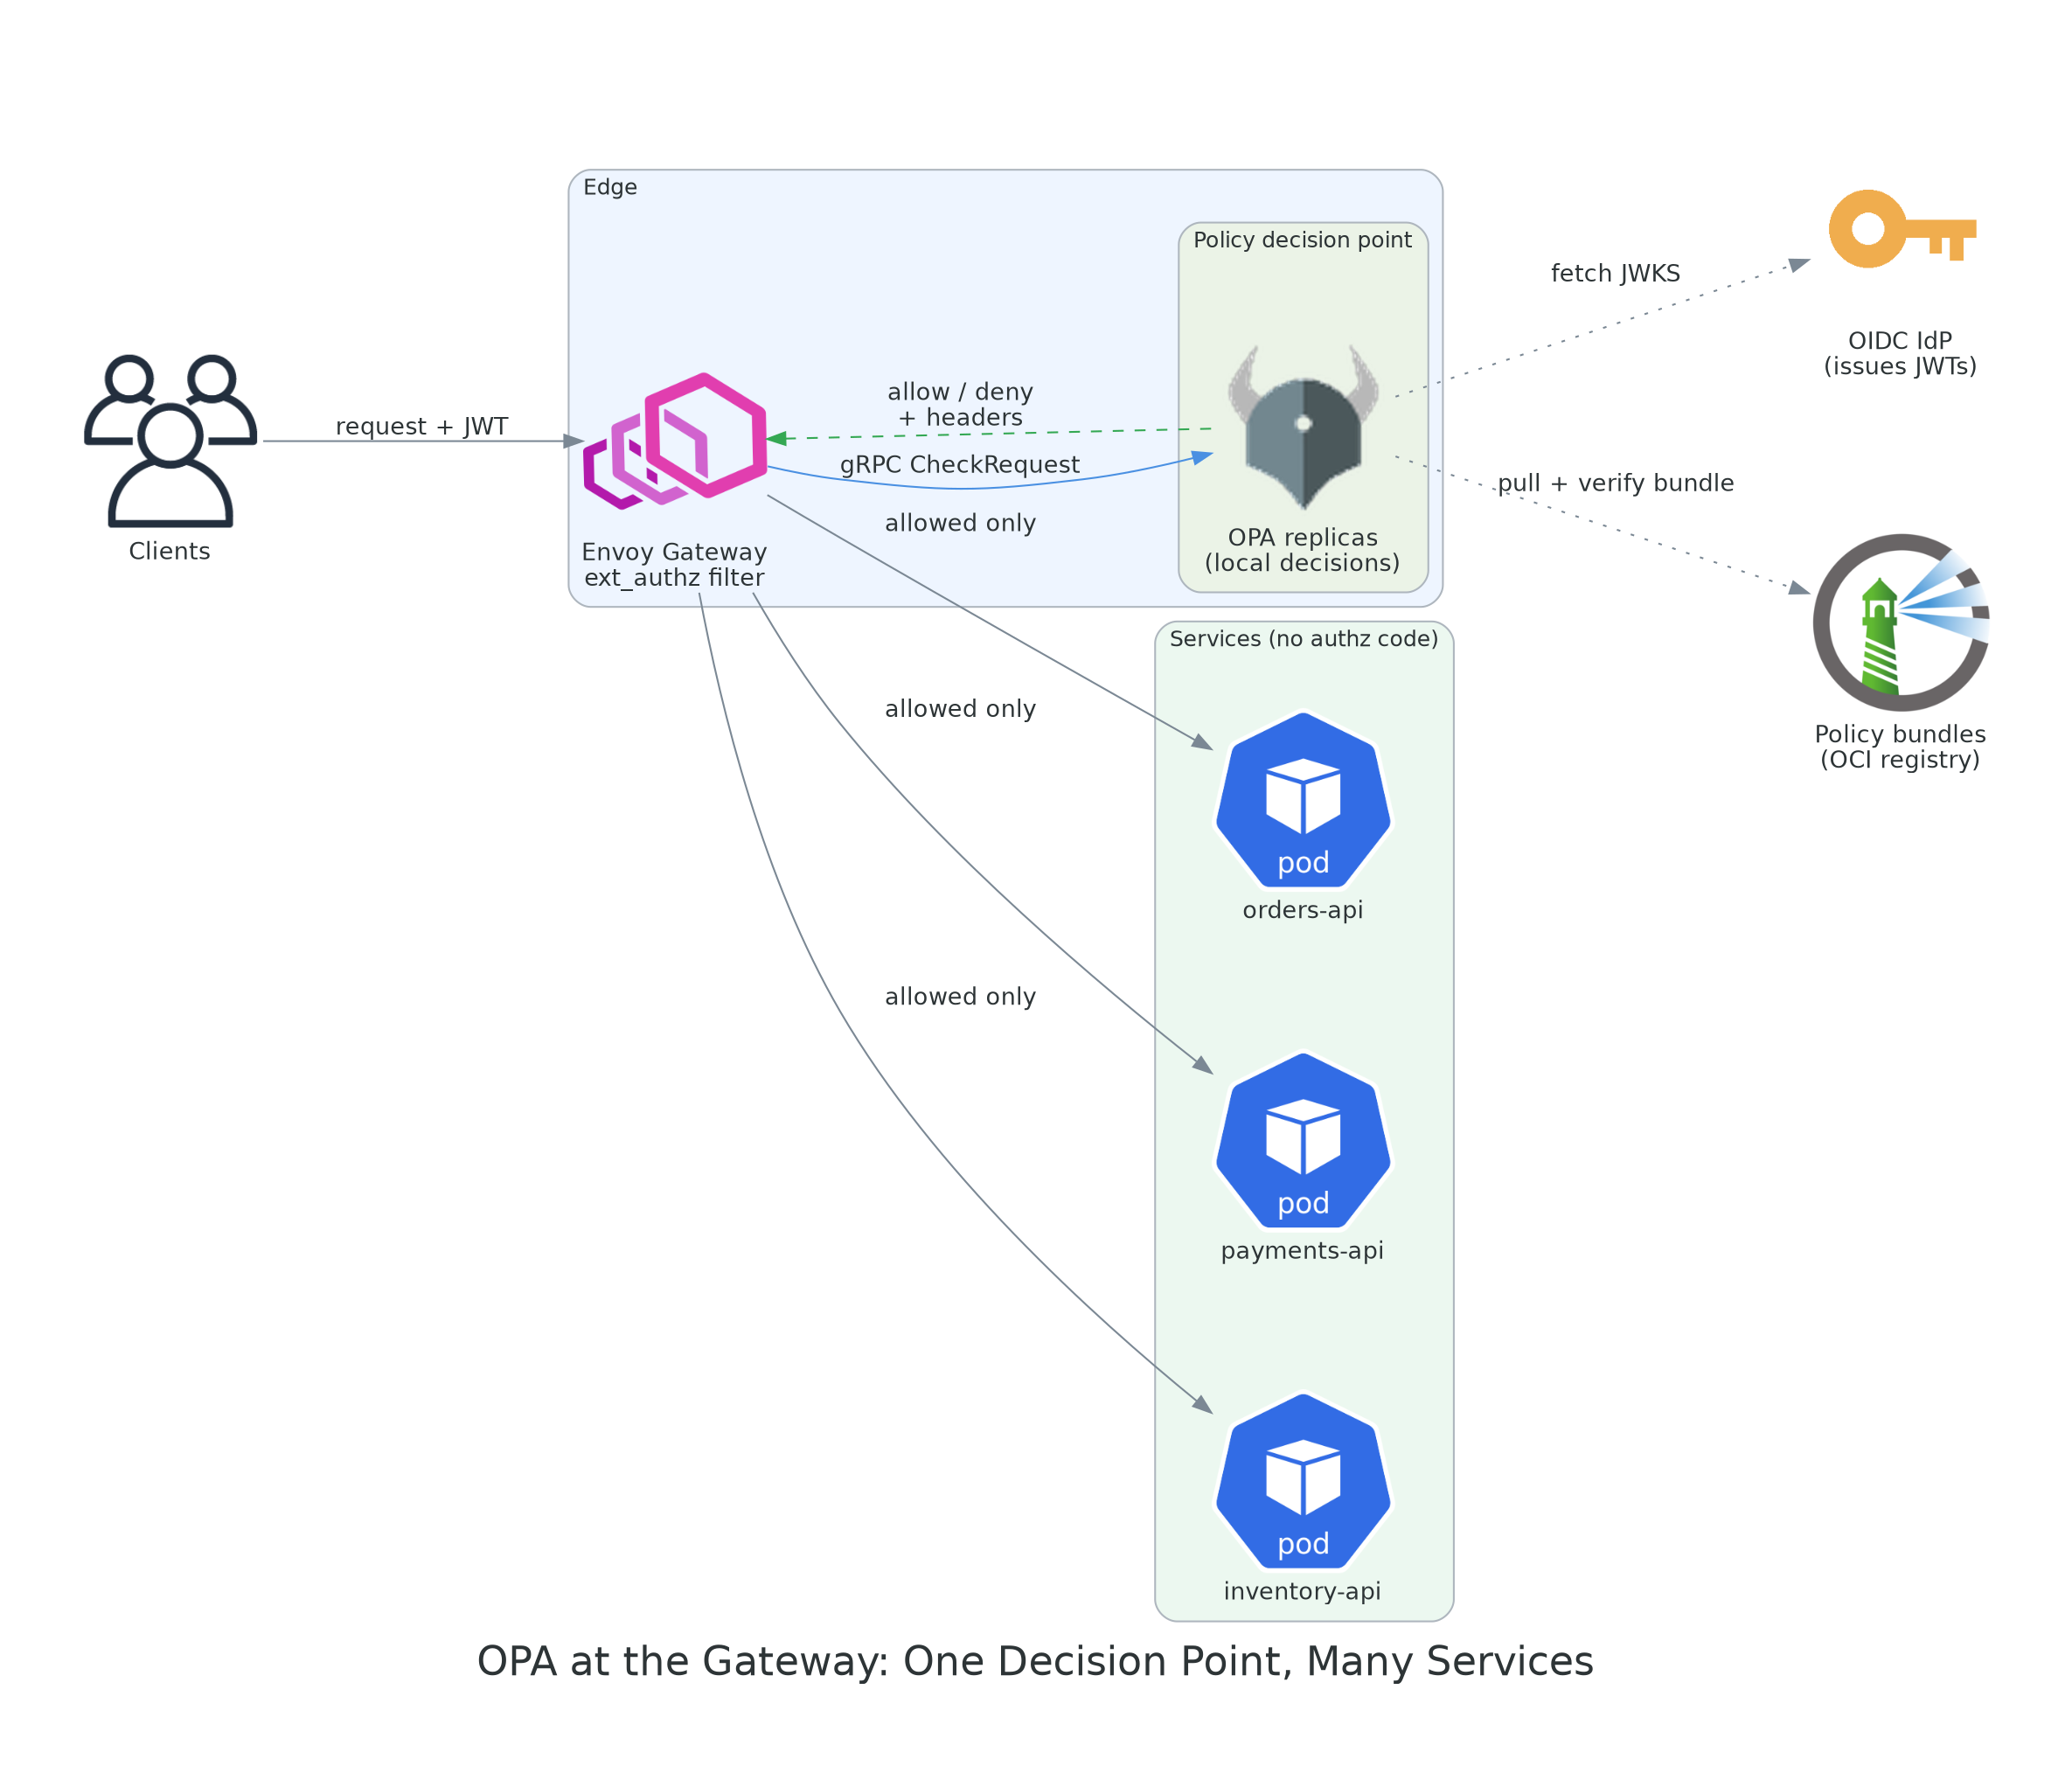
The fix is to separate the decision from the enforcement. The gateway stays the enforcement point it already sees every request. But before forwarding, it asks a dedicated policy engine a single question: should this request go through?
Envoy has had the hook for this for years: the external authorization filter (ext_authz). For each request it sends a gRPC CheckRequest method, path, headers, the verified identity to an authorizer, and waits for allow or deny. OPA speaks that API natively through its Envoy plugin. Envoy Gateway exposes the same hook declaratively through a SecurityPolicy attached to a route, so wiring it up is a Gateway API object in Git rather than a hand-edited Envoy config.
Two details make it work in production. First, OPA decides locally: policies and supporting data are pulled as bundles and held in memory, so a decision is a function call, not a database lookup. Second, the verdict can carry headers back to the upstream a verified user ID, a tenant, a plan tier so services receive facts they can trust instead of re-parsing tokens themselves.
Why not just use Gatekeeper for this?
Same engine, different moment. Gatekeeper evaluates Kubernetes objects at admission time "may this Deployment exist?" It never sees an HTTP request. The gateway pattern evaluates traffic at request time "may this user POST to this invoice?" Most mature platforms end up running both, and sharing one Rego skill set across them is one of OPA's quiet advantages.
Anatomy of a decision
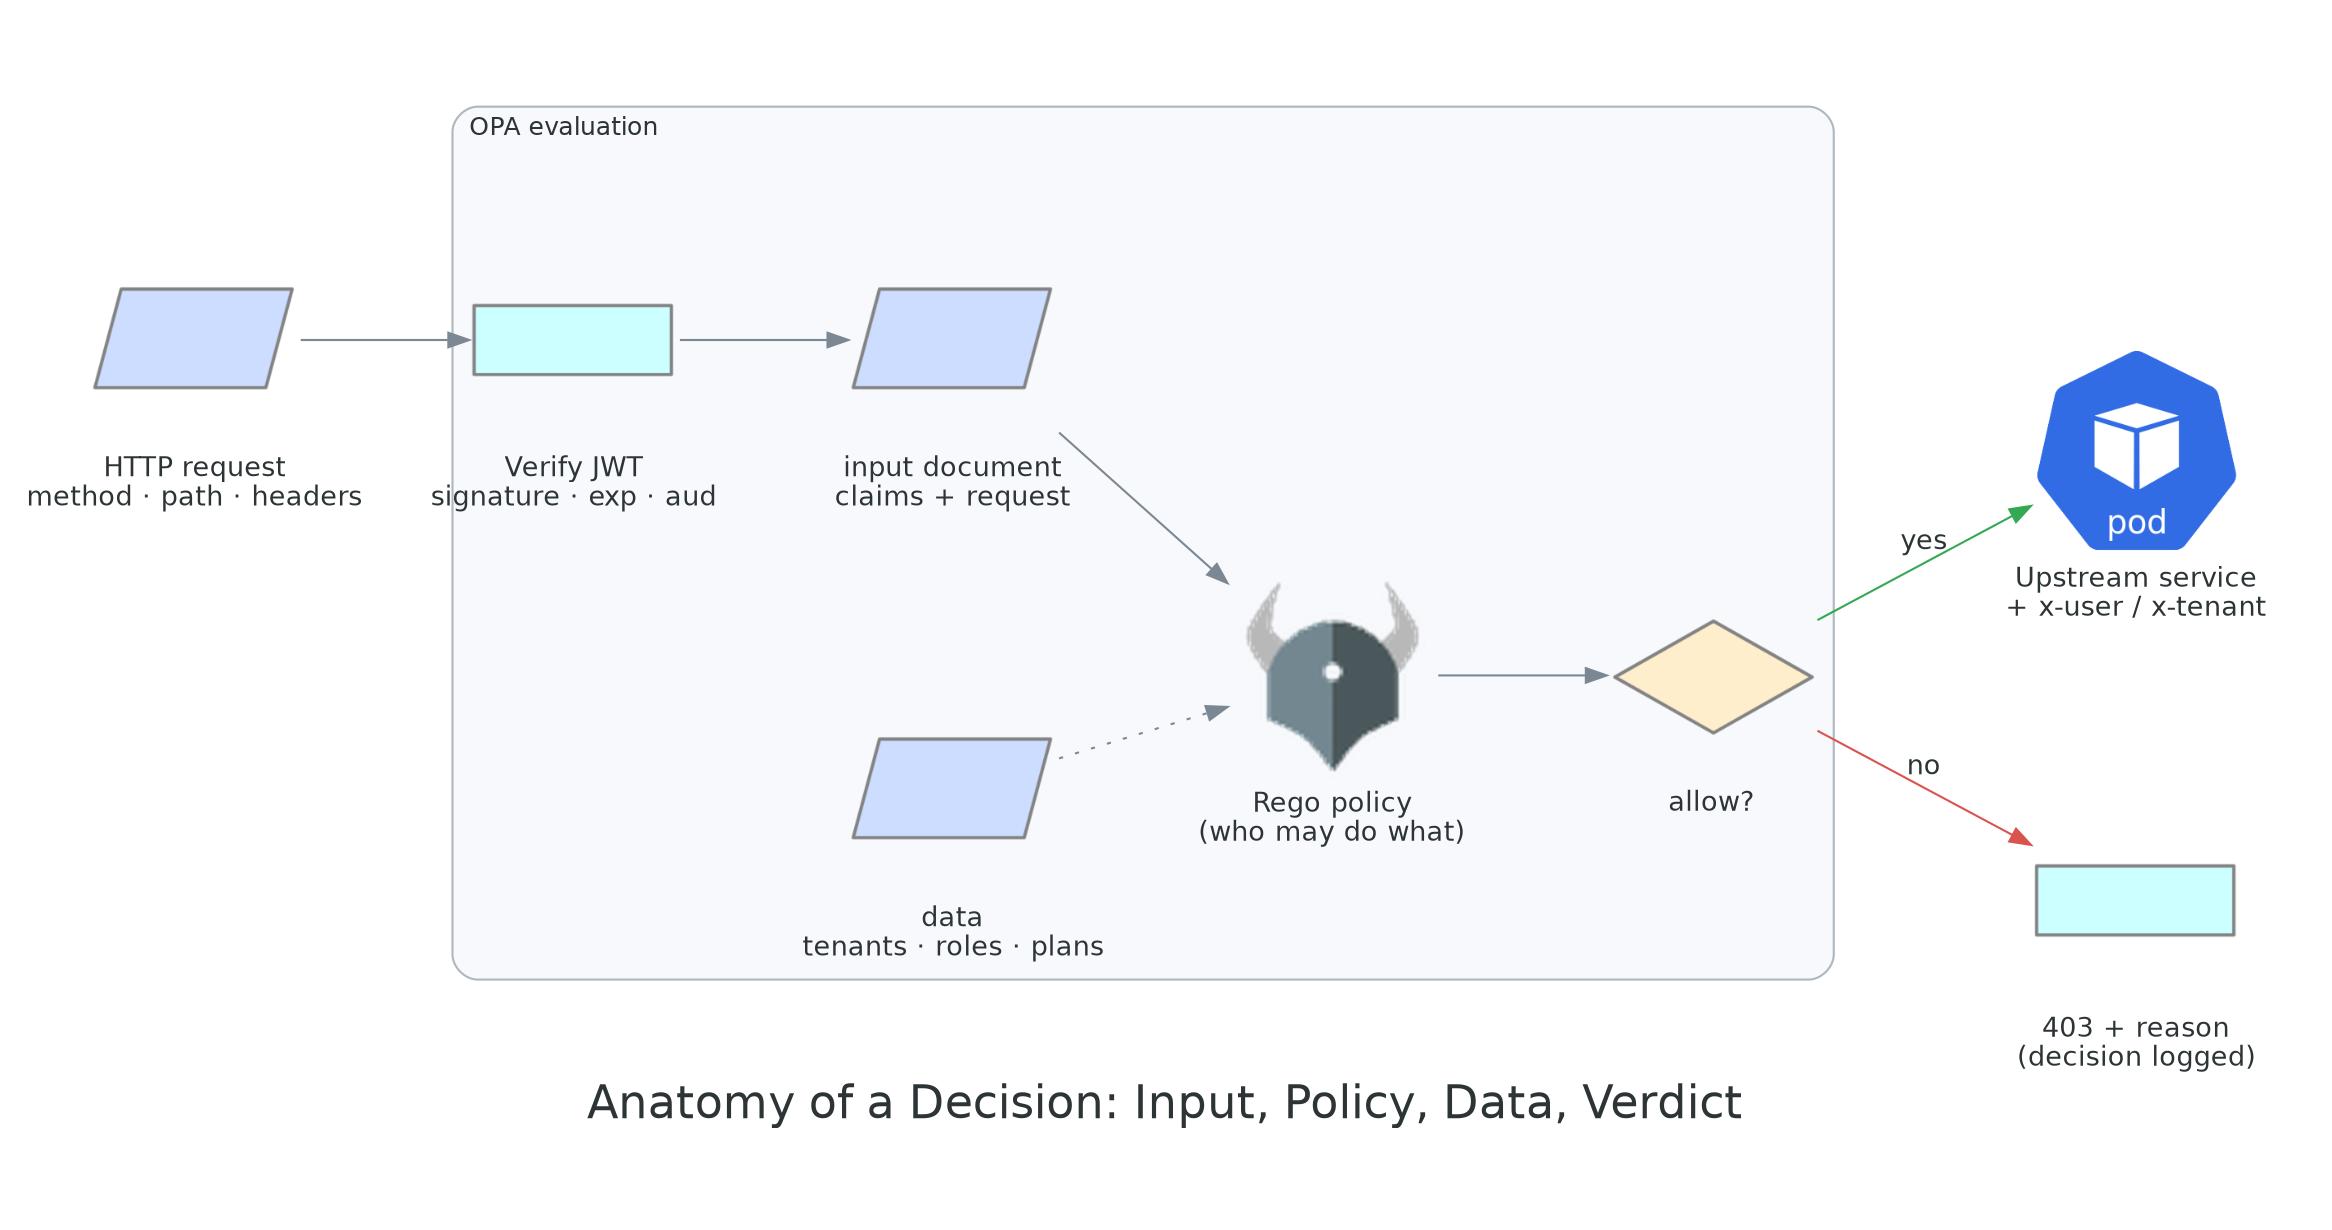
It helps to be precise about what OPA actually evaluates, because that is where good and bad designs diverge.
The policy itself stays small and readable. A realistic rule reads like the business requirement it encodes:
Notice what is not in there: no service name, no framework, no language. The rule is about tenants, roles and resources. That is the whole point the policy describes the business, and any service behind the gateway inherits it without a line of code.
Don't move all authorization to the edge
The gateway knows the request; it doesn't know the row. "May this user edit invoices in tenant A?" belongs at the edge. "May this user edit invoice 4711, which was approved yesterday?" depends on application state the gateway never sees. Put coarse, identity and-route decisions at the gateway and keep object-level checks in the service. Trying to push everything outward is how Rego turns into a second, worse copy of your domain model.
What makes it production-ready: policy as real code
Centralizing authorization concentrates risk. One bad rule no longer breaks one service it can lock out every customer at once, or quietly let everyone in. So the policy lifecycle has to be at least as disciplined as the application lifecycle.
In practice that means policies live in their own repository with unit tests beside every rule, and CI runs opa fmt, opa test, and a coverage gate on every pull request. The most valuable test set isn't written by hand: it's a regression suite of real past decisions anonymized requests with their expected verdicts replayed against every change. A policy edit that flips a historical "allow" to "deny" fails the build before it reaches a user.
Passing builds are packaged as signed bundles and pushed to an OCI registry. OPA replicas poll the registry, verify the signature, and only then activate the new policy. Nobody kubectl execs a Rego file into a pod, and a compromised registry can't inject a rule the pipeline never signed.
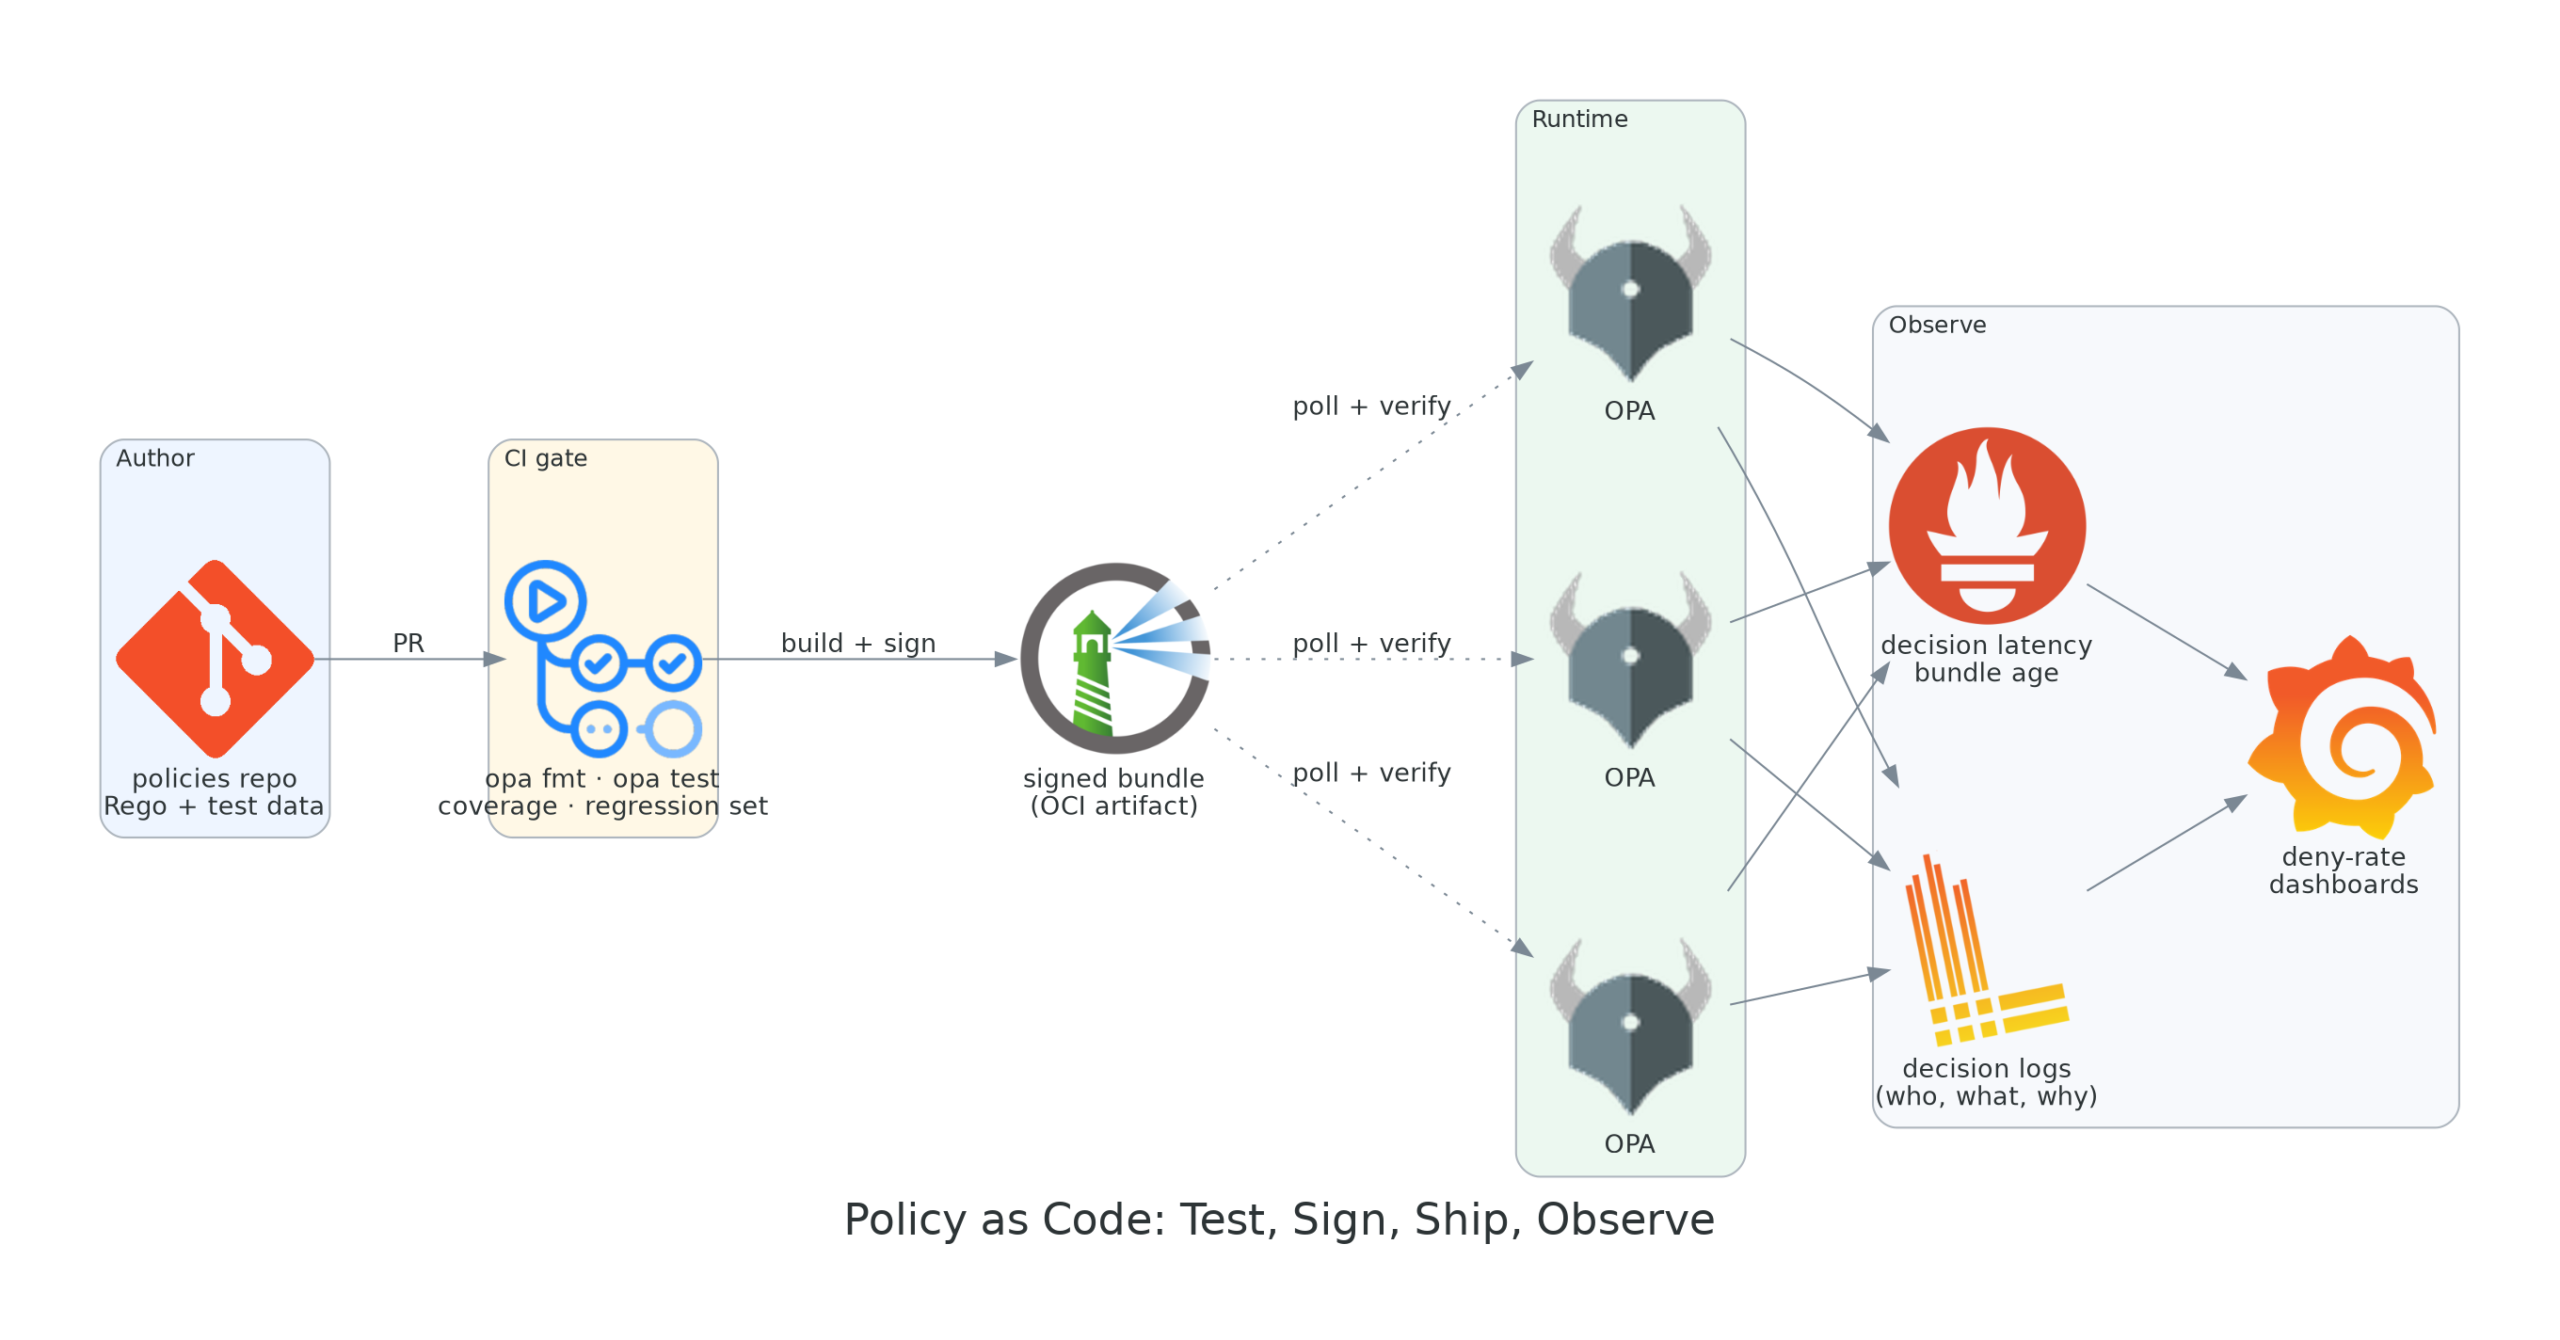
Then close the loop with observability. OPA's decision logs record every verdict with its input and the policy revision that produced it, which turns "why was this user blocked at 14:02?" from a guess into a query. Alongside them, watch three numbers: decision latency (it sits on every request's critical path), bundle age (a replica serving a stale policy is a silent bug), and deny rate per route a sudden spike after a deploy is almost always the policy, not an attack.
The payoff
Authorization becomes a reviewed pull request instead of a cross team archaeology project. Security can read one repository and answer "who can do what" for every API. New services inherit the rules on day one. And every denial has a timestamp, an input and a reason which is exactly what an auditor asks for, and exactly what scattered middleware never produced.
Running OPA next to the gateway
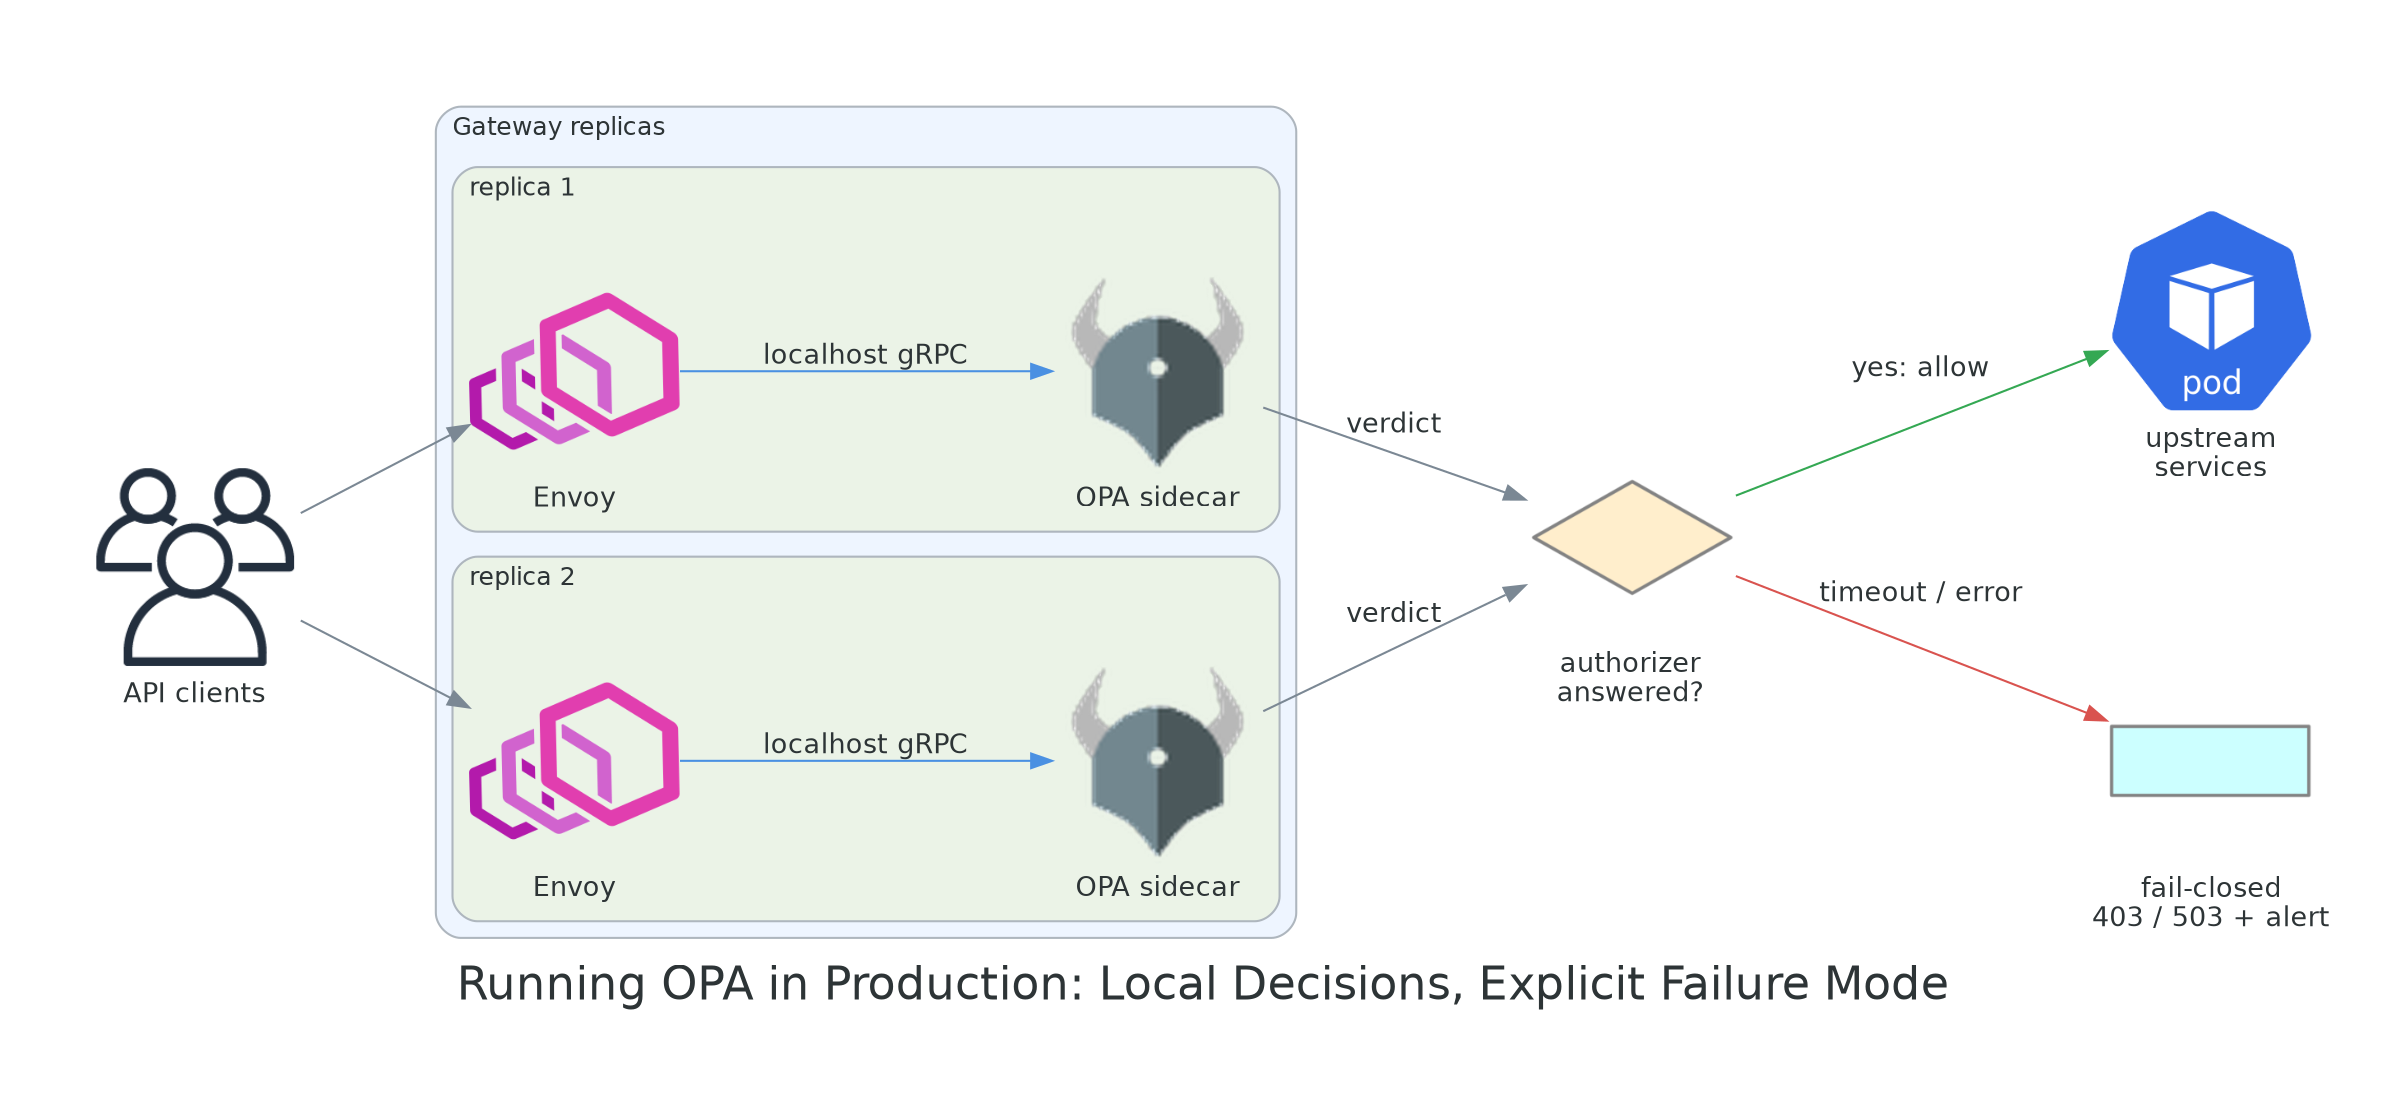
Where OPA runs decides how fast and how fragile the whole pattern is. The robust default is a sidecar in every gateway replica: Envoy asks its local OPA over localhost, so a decision never crosses the network, and scaling the gateway scales the authorizer with it. A shared OPA Deployment is simpler to operate but adds a network hop to every request and turns one Service into a single point of failure for your entire API.
Keep evaluation self contained. A policy that calls out to a database or an HTTP endpoint while deciding makes every request as slow and as available as that dependency. Everything a rule needs role mappings, tenant lists, plan limits should arrive in the bundle, so decisions stay in memory and typically complete in well under a millisecond.
The decision that will page you: fail-open vs fail-closed
Envoy's ext_authz filter has a single setting deciding what happens when the authorizer doesn't answer. Fail-open keeps the site up and silently disables authorization. Failclosed keeps you secure and turns an OPA outage into a full API outage. There is no universally right answer but there is a wrong one: leaving the default unexamined. For anything touching money or tenant data, fail closed, run OPA beside every gateway replica so it's rarely the thing that breaks, and alert on authorizer errors and timeouts before customers notice.
The trade-offs you're signing up for
- A new tier-zero dependency. The authorizer is now as critical as the gateway itself. Treat its upgrades, resource limits and dashboards accordingly.
- Rego is a skill. It's declarative and unlike most languages your team writes. Budget time to learn it, keep rules boring, and reject clever policies nobody else can review.
- Data freshness. Role mappings in bundles are only as current as the last bundle. Revoking an admin shouldn't wait for a ten-minute poll interval decide how urgent changes propagate before you need it.
Where OPA should decide and where it shouldn't
The gateway is not the only place OPA earns its keep, and it shouldn't carry every decision. The same engine and the same Rego skills apply at three distinct moments, each with a clear job and a clear blind spot.
| Where OPA runs | Question it answers | Good at | Blind spot |
|---|---|---|---|
| Admission (Gatekeeper) | May this object exist in the cluster? | Registries, labels, limits, security context | Never sees API traffic |
| Gateway (ext_authz) | May this caller make this request? | Identity, tenant, route and method rules | Doesn't know application state |
| Inside the service | May this user act on this specific record? | Object-level rules with app data in hand | Only as consistent as the teams calling it |
The practical split: let the gateway reject everything that can be decided from who is calling and what route they hit which, in most APIs, is the majority of denials. Let services ask OPA only the questions that need a row from their own database. One policy repository can serve both, so the rules stay consistent even when the enforcement point differs.
OPA Gatekeeper
Guards the cluster's front door for objects: approved registries, required labels, resource limits. The use case the original Gatekeeper announcement made famous.
OPA behind ext_authz
One decision point for every API request. Identity-and-route rules, tested and signed like code, logged with a reason, and enforced before traffic reaches a service.
OPA for object-level checks
The same policy repository answering record-level questions from inside the application, where the data needed to decide actually lives.